
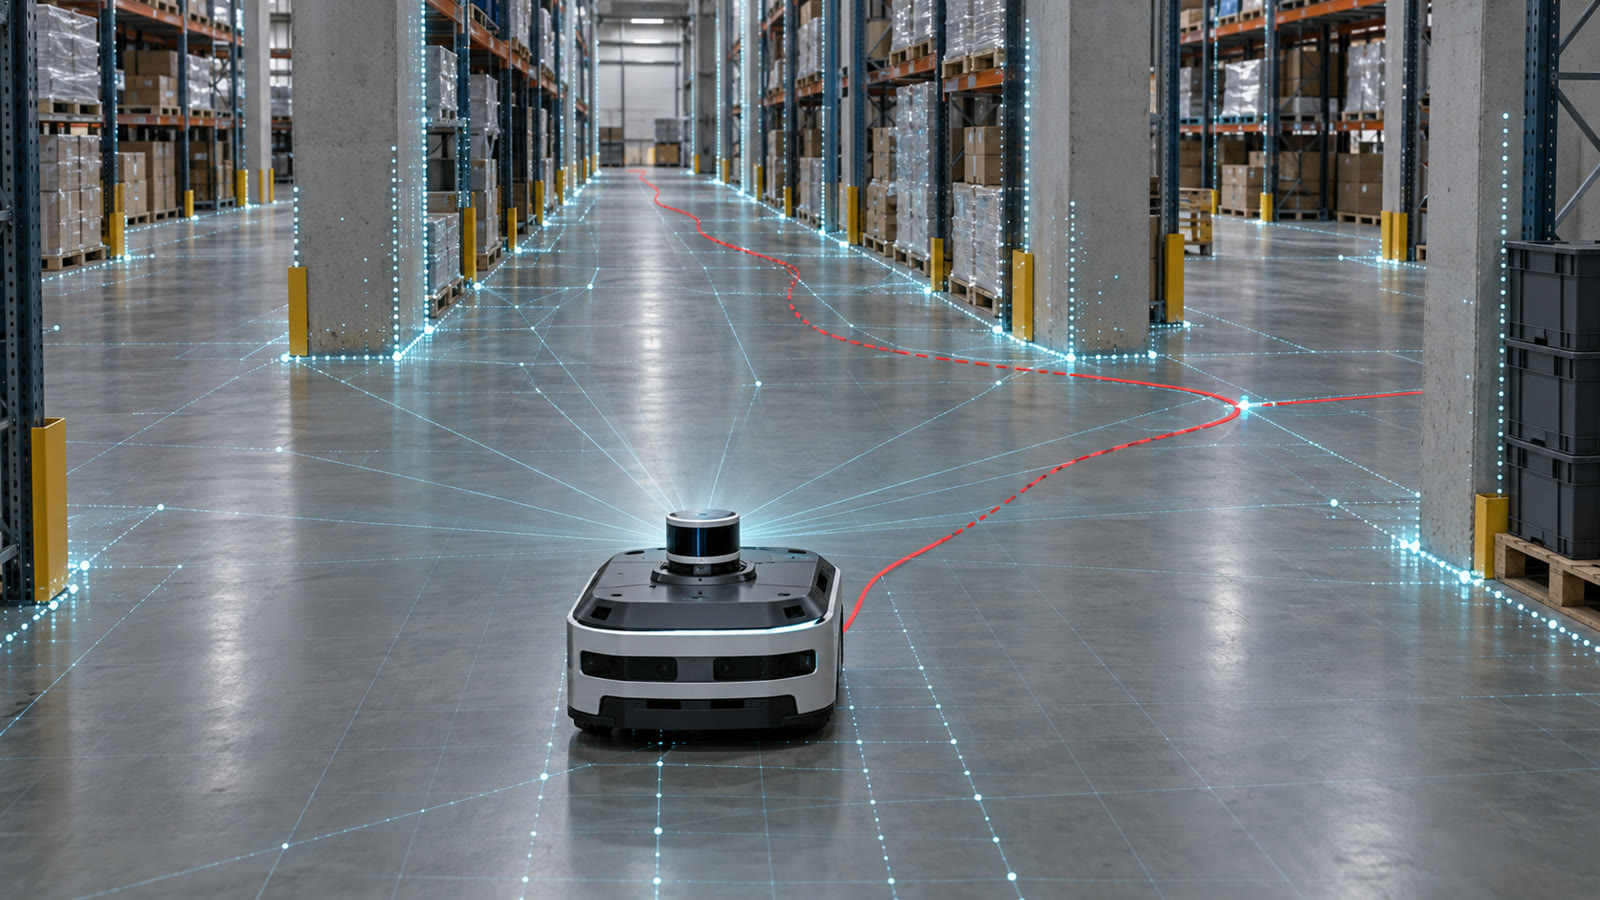
A mobile robot can draw a map while becoming steadily wrong about where it is. Walls look straight, aisles connect, and the route appears smooth, yet a small error in every turn can move the robot’s estimated position meters away from reality after a long trip.
This is the central tension in simultaneous localization and mapping, usually called SLAM. The robot must estimate its motion while using that motion estimate to build a map, then use the evolving map to correct its position. Modern lidar, cameras, inertial sensors, and optimization software make this practical, but they do not remove uncertainty. A useful map system must expose how errors accumulate, when corrections occur, and what happens when the environment changes.
Mapping and localization are different jobs
Mapping estimates the geometry or landmarks of an environment. Localization estimates the robot’s pose, meaning its position and orientation, inside a map. SLAM performs both when no trusted map or external position reference is available. Once a map exists, a deployed robot may switch to localization against that saved representation rather than rebuilding everything continuously.
A map can be an occupancy grid, a point cloud, a set of visual features, a graph of places, or several layers with different purposes. Navigation may need free space and obstacle boundaries, while manipulation or inspection needs more precise landmarks. A beautiful three-dimensional rendering is not necessarily the most reliable representation for planning motion.
Odometry is smooth because it is allowed to drift
Odometry estimates short-term motion from wheel encoders, cameras, lidar scans, inertial measurement units, or a fusion of sensors. Each update is relative to a recent state. Small errors accumulate because the system repeatedly integrates imperfect measurements.
The active ROS REP 105 coordinate-frame convention makes this tradeoff explicit. The odom frame is continuous and useful for local control, but it may drift without a fixed bound. The map frame provides the long-term global reference and can jump when localization corrects an accumulated error. The robot’s physical body is represented by base_link.
That separation prevents a global correction from appearing as an impossible instant motion in the controller. The robot can keep a smooth local trajectory in odom while the transformation between map and odom absorbs the correction.
Every sensor has a characteristic failure mode
Wheel encoders are direct and fast, but slipping tires, uneven floors, load changes, and wheel-radius calibration create error. An inertial unit measures acceleration and rotation, yet small bias becomes large position drift after integration. Cameras offer rich visual landmarks but struggle with darkness, glare, motion blur, blank walls, seasonal change, and repeated textures. A monocular camera also has to infer metric scale.
Lidar provides accurate range geometry, but long uniform corridors and repeated warehouse aisles can look alike. Glass, mirrors, dust, rain, and moving objects can distort returns. Sensor fusion reduces dependence on one modality, but calibration and time synchronization then become part of the problem. A rigid transform that is slightly wrong or a timestamp offset during a turn can produce a systematic mapping error.
SLAM turns measurements into a graph of constraints
Many SLAM systems represent selected robot poses as nodes and measured relationships as edges. Consecutive scans create local motion constraints. Recognized landmarks connect observations to the map. The system optimizes the graph to find a trajectory that best satisfies the constraints while accounting for their uncertainty.
Google’s original Cartographer paper describes a real-time approach that builds local submaps and uses scan matching plus loop closure to reduce accumulated error. Visual systems use related ideas with camera features and bundle adjustment. ORB-SLAM3, for example, combines visual or visual-inertial estimation with place recognition and multi-map reuse.
The optimizer does not discover an absolute truth. It finds the most consistent explanation of available measurements and model assumptions. Incorrect calibration, underestimated noise, or false data association can produce a precise-looking but wrong result.
Loop closure corrects drift by recognizing a return
A loop closure occurs when the robot recognizes that a current observation comes from a place it visited earlier. The new constraint reveals that the accumulated route should reconnect with the old map. Optimization can then distribute the error across many earlier poses instead of placing the entire correction at the current location.
This can visibly bend a corridor into alignment or move distant sections of a map. It is not evidence that the robot teleported. The estimate changed because the system gained information. A navigation stack must keep local motion continuous while accepting that its global position can be revised.
A false loop closure can damage the whole map
Repetitive spaces create perceptual aliasing: two different locations produce similar observations. A warehouse with identical racks, an office with repeated doors, or a road network with similar intersections can trigger an incorrect match. If the optimizer trusts that false constraint, separate places may collapse together or the trajectory may warp.
Robust systems test geometric consistency, require several supporting observations, reject outliers, and track uncertainty. Some can start a new map after losing localization and merge it later when a credible connection appears. Conservative rejection reduces catastrophic errors but may also miss a genuine loop, leaving drift uncorrected.
Dynamic environments make yesterday’s map stale
A saved map often assumes that major structures are static. Real facilities move pallets, shelves, carts, doors, partitions, and parked vehicles. People and other robots create transient observations. If every difference becomes permanent map geometry, the representation fills with ghosts; if the system ignores too much, it can miss a real structural change.
Production deployments often separate a stable localization layer from live obstacle detection and maintain policies for map updates. Changes may require approval, versioning, or a fresh survey. Mixed fleets add another challenge because sensors, coordinate conventions, and map formats differ. Our article on mixed-robot fleet interoperability explains why sharing commands does not automatically create a common world model.
Benchmarks measure trajectories, not complete deployments
The TUM RGB-D benchmark provides synchronized color and depth images with motion-capture ground truth so researchers can compare estimated and real trajectories. The KITTI odometry benchmark uses road sequences for monocular, stereo, lidar, and combined methods. Such datasets support repeatable evaluation with known reference trajectories.
Absolute trajectory error measures global alignment, while relative pose error examines local motion consistency over shorter intervals. Both are useful, but a benchmark score does not capture every deployment condition. A robot may perform well on a recorded route and fail under different lighting, wheel slip, camera exposure, moving crowds, or a rearranged building.
Testing should therefore include the actual operating environment, difficult transitions, repeated structures, sensor obstruction, recovery after localization loss, and long-duration map aging. Our guide to robot accuracy and repeatability makes the same measurement point: consistency and closeness to ground truth are different properties.
A trustworthy deployment reports failure as well as accuracy
Useful metrics include trajectory error against surveyed references, localization confidence, rejected and accepted loop closures, relocalization time, distance traveled before correction, map-update frequency, and intervention rate. Operators also need evidence that clocks, sensor extrinsics, wheel dimensions, and software versions are controlled.
The system should define what happens when confidence falls. It may slow down, stop, return to a known landmark, request assistance, or start a separate map. Continuing at full speed with an uncertain pose converts a mapping problem into a safety and availability problem.
Limitations and what to watch next
No combination of sensors eliminates drift in every environment. External references such as surveyed markers, ultra-wideband anchors, or satellite positioning can bound error, but they add infrastructure, coverage limits, and their own failure modes. Learned visual features may improve place recognition while making performance harder to explain across new sites.
Watch for better lifelong mapping, automatic detection of structural change, uncertainty estimates that are calibrated rather than merely confident, and map standards that allow different robots to share landmarks without confusing coordinate frames. The strongest systems will not claim that their map is the world. They will show how the map was measured, when it was corrected, and when the robot no longer trusts it.
Featured image: AI-generated editorial illustration of lidar mapping, accumulated path drift, and loop closure in a warehouse, not a test of a specific robot.
Leave a Reply